Artificial intelligence is advancing rapidly, with new models becoming more powerful and capable of handling complex tasks. However, building a larger AI model does not automatically guarantee better results. The quality of the data used to train, test, and improve that model plays an equally important role.
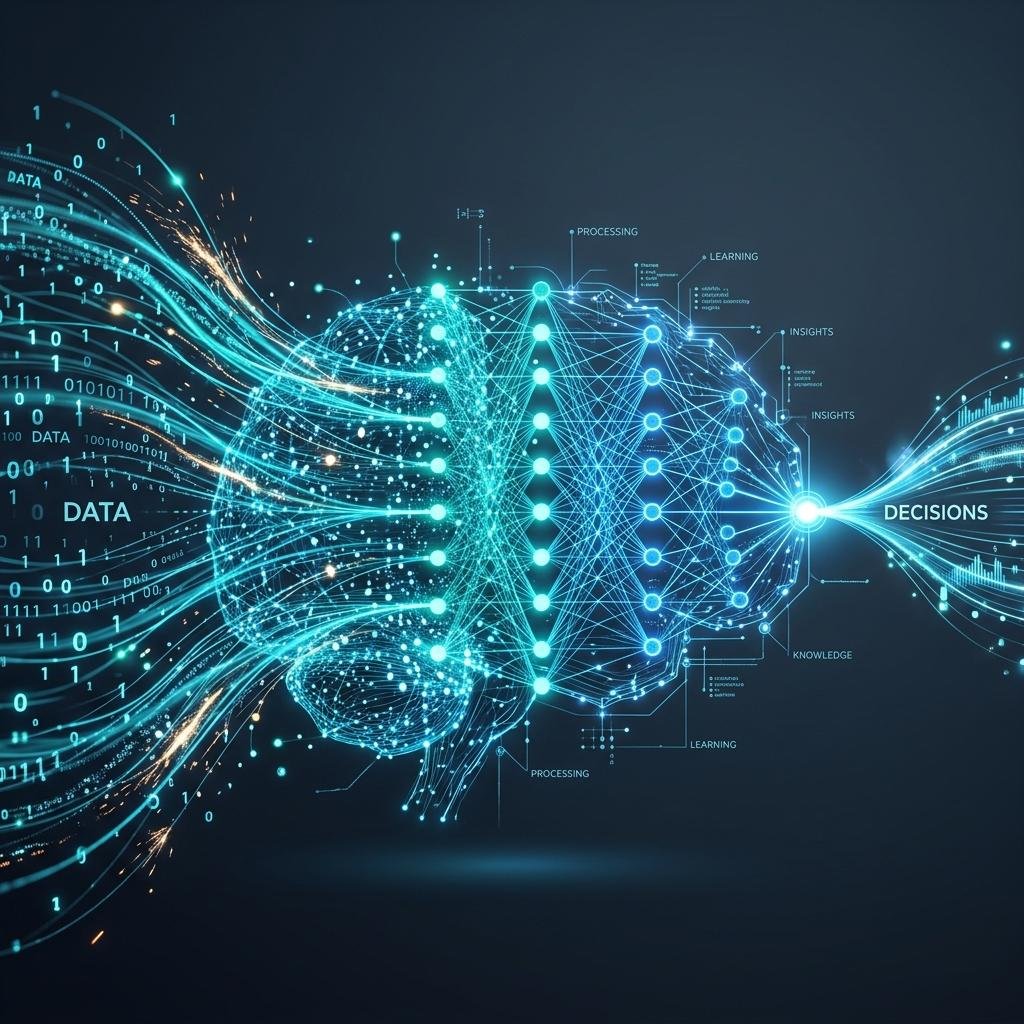
This is where data-centric AI comes into focus. Instead of concentrating only on model architecture, computing power, or increasing the number of parameters, this approach prioritizes improving the data that AI systems learn from. Clean, accurate, relevant, and well-organized data can help an AI system produce more reliable and useful outcomes.
For businesses, researchers, and technology teams, this shift raises an important question: Is it better to build a bigger model or make better use of the data already available?
What Is Data-Centric AI?
Data-centric AI is an approach to artificial intelligence that focuses on systematically improving the quality of datasets rather than making frequent changes to the model itself.
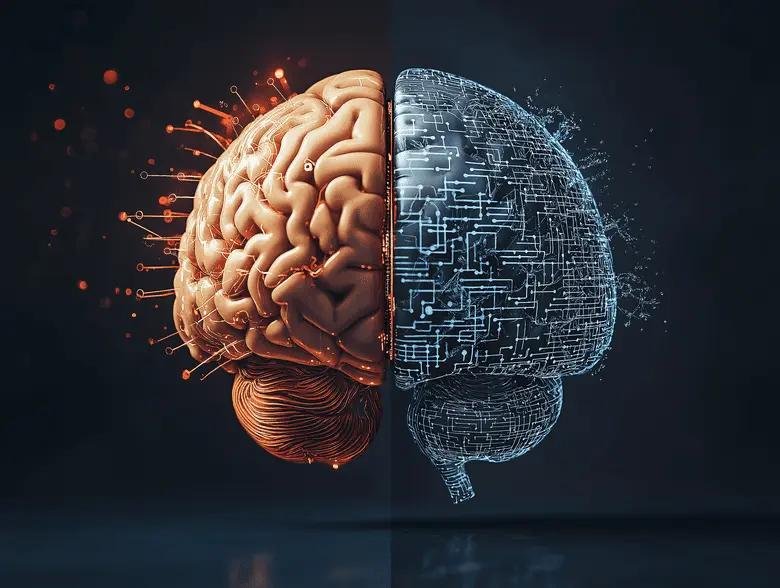
Traditional AI development often emphasizes model-centric improvements, such as selecting a different algorithm, adjusting parameters, or increasing model complexity. Data-centric AI takes another route by examining the information used to train and evaluate the system.
This may involve correcting mislabeled records, removing duplicate entries, addressing missing information, balancing underrepresented categories, and ensuring that training examples accurately reflect real-world conditions.
For example, an AI system designed to identify manufacturing defects may struggle if its training images contain inconsistent labels or fail to represent different types of defects. Improving the dataset could help the existing model recognize problems more accurately without requiring a significantly larger architecture.
The goal is not to ignore model development. It is to ensure that data receives the attention it needs throughout the AI development process.
Why Data Quality Matters More Than Model Size
A larger AI model can learn complex patterns, but its performance still depends on the quality and relevance of the information it receives. When the underlying data is incomplete, outdated, biased, or inaccurate, increasing model size may not solve the fundamental problem.
Several factors explain why data quality deserves greater attention.
1. Better Data Produces More Reliable Predictions
AI systems learn patterns from examples. If those examples contain errors, the system may learn misleading relationships or make incorrect predictions.
Consider a company developing an AI tool to forecast product demand. If its historical sales data contains duplicate transactions, incorrect inventory figures, or missing seasonal information, the resulting predictions may be unreliable.
Correcting these issues can give the model a more accurate foundation for learning. This helps teams improve the consistency of their results and make better-informed decisions.
2. High-Quality Data Can Reduce Unnecessary Costs
Training and operating large AI models can require substantial computing resources, infrastructure, and engineering time. However, increasing model complexity is not always the most efficient way to improve performance.
A carefully prepared dataset may allow a smaller model to achieve the required accuracy for a specific business task. This can reduce training expenses, simplify deployment, and make AI applications easier to maintain.
The actual savings depend on the use case, dataset, model, and performance requirements. Nevertheless, data improvement provides an important alternative to automatically increasing model size.
3. Representative Data Helps Identify Bias
AI systems can produce unfair or inconsistent results when their training data does not adequately represent the people, environments, or situations they encounter.
For instance, a computer vision system trained primarily on images collected under bright lighting may perform poorly in darker environments. The problem may not be the model’s size but the limited variety of its training examples.
Data-centric practices help teams identify missing categories, examine representation gaps, and include examples that better reflect real-world conditions.
Although improved data can reduce certain forms of bias, it cannot eliminate every source of unfairness. Responsible AI development also requires careful evaluation, appropriate safeguards, and ongoing monitoring.
4. Relevant Data Helps AI Adapt to Changing Conditions
Data that was accurate several years ago may no longer reflect current business operations, customer behavior, scientific findings, or market conditions.
An AI model trained on outdated information can gradually become less useful as the environment changes. Regularly checking data freshness and updating relevant examples helps organizations maintain the practical value of their AI systems.
This is particularly important in areas such as fraud detection, demand forecasting, cybersecurity, and scientific research, where new patterns can emerge quickly.
Data-Centric AI vs. Model-Centric AI
Both approaches contribute to AI development, but they emphasize different areas of improvement.
| Aspect | Data-Centric AI | Model-Centric AI |
|---|---|---|
| Main focus | Improving data quality and consistency | Improving model design and architecture |
| Common activities | Cleaning labels, correcting errors, balancing datasets | Adjusting parameters, changing algorithms, increasing model capacity |
| Primary objective | Help the model learn from better examples | Help the model learn more effectively through model improvements |
| Potential benefit | More reliable training data and predictions | Better performance when model limitations are the main issue |
| Main challenge | Obtaining accurate, representative, well-maintained data | Managing complexity, computing requirements, and development costs |
Neither approach is universally superior. If a model is too simple for a complex task, a stronger architecture may be necessary. If the dataset contains major errors, however, a more powerful model may simply learn from those errors more effectively.
In many practical projects, the best results come from combining both approaches.
How Businesses Can Apply Data-Centric AI
Organizations do not always need to rebuild their AI infrastructure to begin improving data quality. They can start with targeted changes to the datasets that support their most important applications.
Audit Existing Datasets
Begin by examining the information currently used to train and evaluate AI systems. Look for duplicate records, missing values, inconsistent formatting, incorrect labels, outdated entries, and unexpected patterns.
A structured data audit can help teams identify which problems are most likely to affect model performance.
Improve Data Labeling
Supervised machine learning depends on examples that have been assigned meaningful labels. Incorrect or inconsistent labels can confuse a model and reduce its ability to distinguish between categories.
Organizations should establish clear labeling guidelines, use quality checks, and investigate disagreements between annotators. For specialized tasks, subject-matter experts may be needed to validate difficult examples.
Measure Data Quality Continuously
Data quality should not be treated as a one-time cleanup project. New information enters systems continuously, and existing datasets may become less relevant over time.
Teams can monitor measures such as completeness, accuracy, consistency, duplication, and freshness. They can also track how changes to a dataset affect model performance on a separate evaluation set.
Use Evaluation Data Carefully
A model should be tested using data that represents the situations it will encounter in practice. Teams should keep appropriate evaluation datasets separate from training data to avoid misleading performance estimates.
For example, a model intended to identify unusual financial transactions should be evaluated on examples that reflect realistic transaction patterns, including relevant rare events.
Careful evaluation helps organizations determine whether an improvement comes from better data, a different model, or another change in the development process.
Real-World Applications of Data-Centric AI
Data-centric AI can support a wide range of industries, especially where data accuracy directly affects decisions.
Healthcare and medical research: Researchers can improve dataset consistency, correct annotations, and examine gaps in patient representation. These steps can support more dependable research findings, although clinical systems still require rigorous validation and appropriate oversight.
Manufacturing: Industrial teams can improve sensor records, standardize defect labels, and collect examples from different operating conditions. Better data can help predictive maintenance and quality inspection systems identify relevant patterns.
Financial services: Banks and financial technology companies can examine transaction records for errors, improve fraud labels, and account for changes in customer behavior. These practices can strengthen model evaluation and help teams detect weaknesses in their data.
Scientific research: Scientists can standardize experimental records, document data sources, and improve the reproducibility of machine learning experiments. More consistent datasets make it easier to compare results and investigate unexpected findings.
Retail and e-commerce: Businesses can clean product catalogs, improve inventory records, and combine reliable sales data with relevant seasonal information. These improvements can support demand forecasting and product recommendations.
Across these applications, the objective is similar: give AI systems information that accurately reflects the problem they are expected to solve.
Challenges in Adopting Data-Centric AI
Despite its advantages, data-centric AI requires careful planning and sustained effort.
One challenge is that data may be scattered across disconnected systems, departments, or storage platforms. Combining these sources can introduce inconsistent formats and conflicting definitions.
Another challenge is the cost of verifying and labeling data. Specialized datasets may require experienced professionals, particularly in scientific, industrial, and medical applications.
Privacy and security also matter. Organizations must handle personal or confidential information responsibly and follow applicable legal and regulatory requirements.
Finally, better data does not guarantee better outcomes in every situation. Improvements must be measured against clear objectives, and teams should determine whether the main limitation comes from the dataset, the model, the evaluation method, or the surrounding system.
A successful data-centric strategy therefore combines technical processes with clear ownership, documentation, governance, and ongoing performance checks.
The Future of AI: Better Data and Smarter Models
As AI systems become more widely used, the ability to collect more information will not necessarily be the biggest competitive advantage. Organizations will also need to understand which data is trustworthy, which examples are relevant, and where important information is missing.
Data-centric AI encourages teams to treat datasets as assets that require continuous improvement rather than as fixed inputs to a model. This mindset can support more efficient development, clearer evaluation, and better alignment between AI systems and real-world requirements.
At the same time, advances in model architecture remain important. Larger models can offer valuable capabilities for complex reasoning, language understanding, and other demanding tasks. The practical challenge is to determine when greater model capacity is useful and when improving the underlying data offers a better path forward.
Conclusion
Data-centric AI highlights a fundamental principle of artificial intelligence: model performance depends not only on how a system is built but also on the quality of the information it learns from.
Accurate labels, representative examples, consistent records, and reliable evaluation data can help AI systems produce more dependable results. In some applications, these improvements may deliver greater value than simply increasing model size.
For organizations investing in AI, the most effective strategy is not necessarily to choose between better data and bigger models. It is to understand the limitations of each system, improve the areas that matter most, and measure the results carefully.
Ultimately, better data gives AI a stronger foundation for making useful predictions, supporting research, and solving real-world problems.
Frequently Asked Questions
1. What is data-centric AI?
It focuses on improving data quality to make AI systems more accurate and reliable.
2. Why is data quality important in AI?
Good-quality data helps AI models reduce errors and make better predictions.
3. How does data-centric AI differ from model-centric AI?
Data-centric AI improves datasets, while model-centric AI improves model design.
4. How can businesses improve AI data quality?
Businesses can clean datasets, correct errors, remove duplicates, and update outdated information.